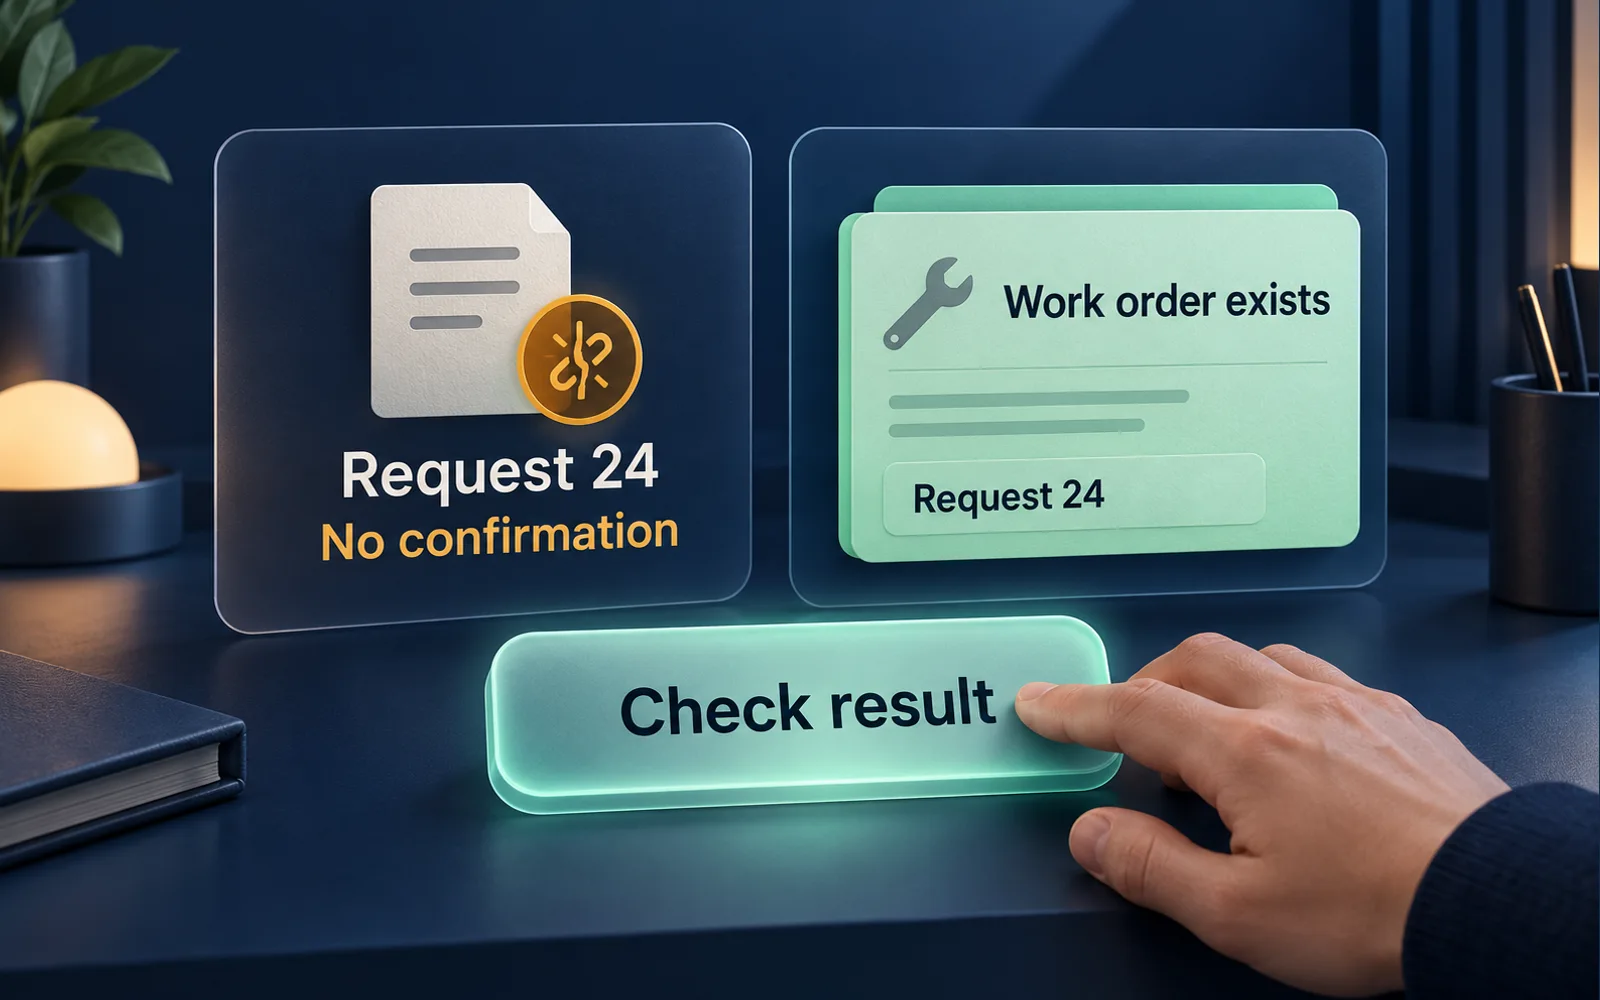
A missing reply leaves the outcome uncertain
A timed-out tool call can leave an AI agent without confirmation even when the destination has completed the requested change. Before repeating a write, check the destination’s recorded outcome using a reliable operation reference. If the system cannot establish what happened, pause the action and give an accountable person the evidence needed to investigate.
This matters when an agent creates a work order, updates a record or sends a message. The retry rule belongs in the surrounding integration and operating process. A prompt asking the model to avoid duplicates is not enough to establish the destination’s state.
Follow the write and the reply separately
Consider a synthetic example. A service team’s assistant requests a new work order. The work-order system saves it, but the reply is lost before the assistant receives confirmation. The assistant sees an error and submits the same request again. Without a suitable duplicate-handling mechanism, the team may now have two work orders for one request.
The useful question is whether the original operation completed. Record the intended action, its reference, the destination and the observed result. Keep an unknown outcome visible instead of converting it into either a success message or an instruction to try again.
Give one intended action a stable identity
Where the receiving service supports duplicate-safe requests, agree how a logical operation is identified and how a repeated request is handled. An identifier added only to an agent’s notes does not make the receiving service recognize a duplicate.
Our proposed integration review asks who stores the operation reference, which destination and account it applies to, how long the result is retained, and what happens if two attempts arrive together. Ask the integration owner how an existing reference behaves when the requested content changes. Those details must come from the actual service contract and implementation.
Treat a changed recipient, work item or instruction as a new decision to assess. An earlier approval should not silently authorize a different action. These rules belong alongside the human approval boundaries for AI agents.
Confirm the retry contract before enabling writes
RFC 9110’s HTTP semantics advises against automatically retrying a non-idempotent request unless the client can establish that its semantics support repetition or that the original request was not applied. The standard does not make every business operation duplicate-safe.
For a proposed AI tool, have the owner demonstrate the destination’s documented retry behavior and a way to look up the original result. A request identifier, status endpoint or equivalent record must actually support the intended decision. If the destination offers no reliable outcome check or duplicate handling, reduce the automation’s authority and keep uncertain writes with a person.
An AI agent integration should expose these limits before it is allowed to change operational records. The model should not invent a status, manufacture a new reference to bypass a conflict, or retry an unresolved write indefinitely.
Make the recovery task usable
A person reviewing an unknown outcome needs the intended change, the operation reference, the affected destination and the results of any status checks. Provide enough context to inspect the destination without unnecessarily copying customer data into logs.
Name the owner who can confirm the outcome, resolve a duplicate or authorize a new attempt. Define a bounded retry policy, escalation conditions and a way to stop further attempts. NIST’s AI RMF Manage Playbook includes monitoring, incident response and recovery in post-deployment planning. The operation record and escalation method here are our proposed implementation approach, not a prescribed NIST form.
Test the uncertain cases before release
Use synthetic records in an isolated test environment. Include a failure before the write, a lost reply after the write, two concurrent attempts, an unavailable status lookup and a changed action after approval. Have the process owner specify the expected destination state and escalation outcome before running each case.
Inspect the destination records as well as the assistant’s final message. Check whether the same intended action was repeated, whether a changed action was incorrectly treated as the original, and whether an unresolved result reached the right owner. Record the work needed to investigate failures rather than measuring only how quickly the assistant replies.
NIST’s Measure Playbook emphasizes testing against the intended use and documenting limits. A small set of passing cases does not establish reliability across every integration or failure condition. Keep monitoring and recovery responsibilities explicit in ongoing AI operations work.
Start with one action and its exception path
Choose one bounded write operation and map the normal result, an uncertain result and the person responsible for recovery. Establish the receiving service’s behavior before giving an agent authority to execute the action. Use fixed integration rules wherever they are sufficient.
AI Gaur can help scope an integration and failure-recovery assessment with agreed deliverables, test cases and acceptance criteria. Bring one workflow and a description with confidential details removed to discuss the tool boundary and recovery process. Delivery effort, operating costs and ongoing support should be agreed separately; no measured time-saving or reliability outcome is claimed here.
Sources checked 31 October 2026. NIST’s Playbook is voluntary risk-management guidance and currently notes that AI RMF 1.0 is being updated.
Sources
- IETF RFC 9110: HTTP idempotent-method and retry semantics
- NIST AI RMF Playbook: Manage, monitoring and recovery
- NIST AI RMF Playbook: Measure, use-context testing and limits
Written by AIGaur, a product and technology company in Edison, New Jersey. About the company.
Discuss a related project